Two prototypes for Perplexity Computer · independent, not made by or with Perplexity
Same prompt, three runs, three prices.
I measured 27 runs of Computer on my own account. Here are two moments where it leaves you guessing, and what I'd build so it doesn't.
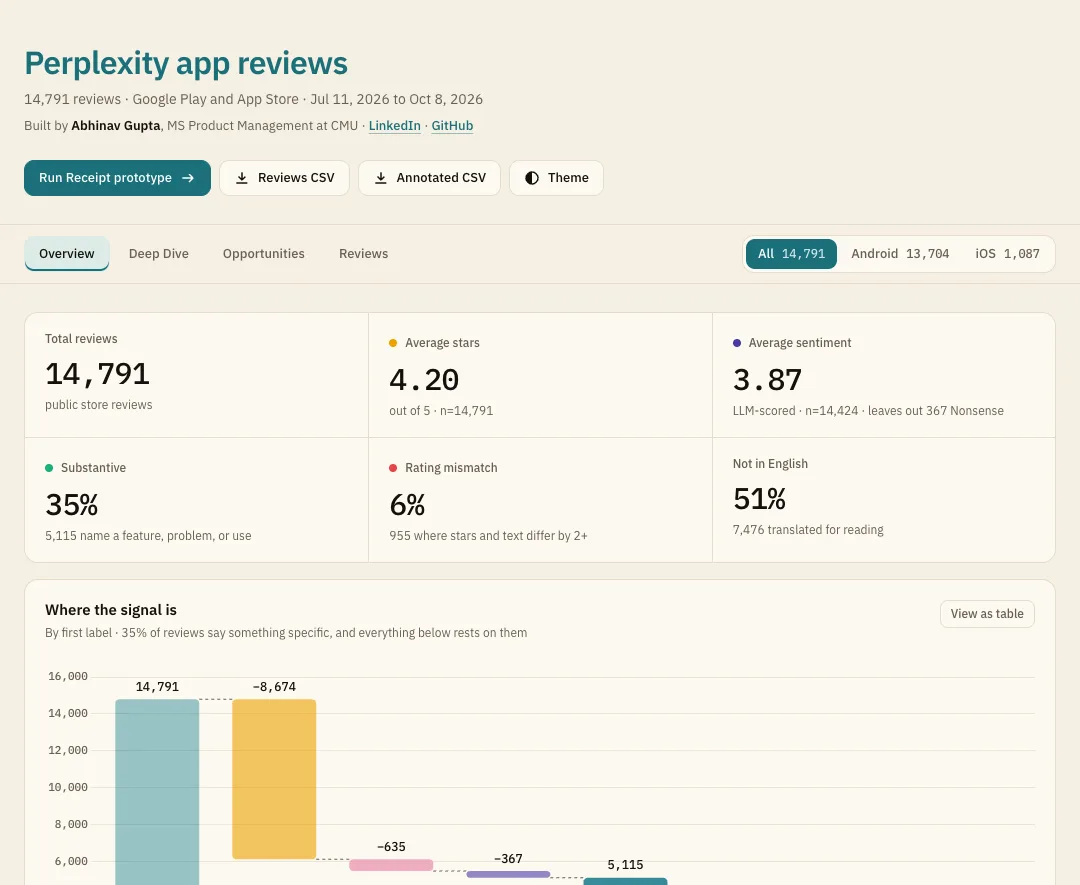 Real customer data, analyzed14,791 public app reviews, labelled and charted · open the dashboard ↗
Two prototypes, one idea
Computer should tell you what a run will cost, and remember the work you keep repeating.
How we'd know it worked
Each prototype has one number that decides it. Both roll up to one Perplexity-level goal.
I have no Perplexity data, so there are no real baselines; every bar is a proposal. The Perplexity-level goal is my assumption.
Why listen to me
I didn't guess. I ran the tasks on my own account, recorded every credit, and graded the results against files with a known answer.
How: I labelled 14,791 public app reviews in a reviews dashboard, then ran 27 measured runs across 11 task types before designing anything (evidence).
Abhinav Gupta. MS Product Management at Carnegie Mellon (Tepper), December 2026. About six years in product, growth and strategy at Flipkart, ShareChat, Meesho and Tata 1mg. I ran the study, built the dashboard and built these prototypes, with Claude Code as a coding partner.
- 27
- measured runs of Computer, Oct 2 to Oct 8, 2026
- 11
- task types, from bank reports to price lookups
- 14,791
- app reviews read and labelled
- 2
- working prototypes
One account, one Mac, one week. Every comparison is a count, not a rate.
What's real and what's simulatedRead before you quote a number
- Real: the credits, times and results of 27 runs on my own account, Oct 2 to Oct 8, 2026, and the review counts and quotes from the dashboard (Jul 11, 2026 to Oct 8, 2026).
- Simulated: both prototypes replay recorded runs and do not connect to Perplexity. The test files are made up. The skill offer, the one-click build and the slash command are my proposal.
- Not yet done: testing either prototype with Perplexity users.